Back to Development Hub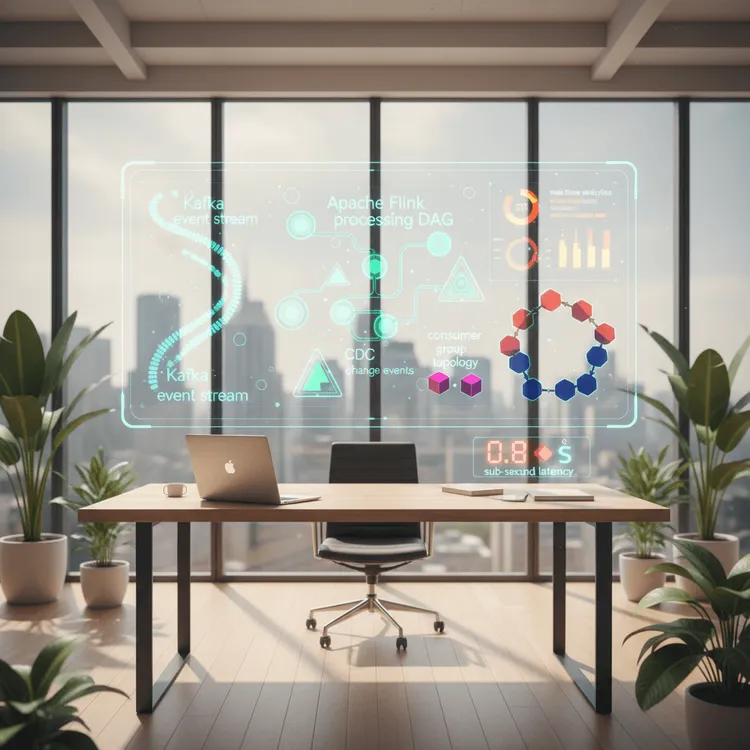
Database & Data
Real-Time Data Processing
Real-time data processing and streaming solutions. We build event-driven systems using Kafka, Flink, and Spark Streaming for sub-second data processing at scale.
Get Started99.9%
Uptime Achieved
3x-10x
Query Speed Gains
Zero
Data Loss
24/7
Support Available
Service Category
Real-Time Data Engineering
Ideal For
Applications requiring sub-second data processing — live analytics, fraud detection, IoT, and event-driven systems.
Timeline
4 – 10 weeks

Why Choose MicrocosmWorks for Real-Time Data Processing?
Batch processing is no longer enough — modern applications need real-time data. We design and implement streaming architectures that process millions of events per second with sub-second latency. From event ingestion to real-time analytics, we build systems that keep your data fresh and your users informed.
Our Real-Time Processing Capabilities
- Event Streaming Architecture — Design event-driven systems using Apache Kafka, Redpanda, or cloud-native services for reliable, ordered event processing.
- Stream Processing — Build real-time transformations, aggregations, and enrichments using Flink, Spark Streaming, or Kafka Streams.
- Real-Time Analytics — Create live dashboards, real-time metrics, and streaming aggregations that reflect your business state in seconds, not hours.
- Event Sourcing & CQRS — Implement event-sourced systems with command/query separation for complete audit trails and temporal query capabilities.
- CDC (Change Data Capture) — Set up database change streaming with Debezium for real-time data synchronization between systems.
- Alerting & Anomaly Detection — Build real-time monitoring that detects anomalies, triggers alerts, and initiates automated responses within seconds.
Technology Stack
We build with Apache Kafka for event streaming, Apache Flink for stateful stream processing, Debezium for CDC, and ClickHouse or Druid for real-time OLAP. Deployment on Kubernetes with proper backpressure handling, exactly-once semantics, and comprehensive monitoring.
Who This Is For
Applications requiring real-time data — fraud detection, live analytics, IoT processing, real-time personalization, or event-driven microservices. If your batch processes introduce unacceptable delay, we design streaming architectures that deliver data when it matters most.
Our Process
1
Requirements Analysis
Define latency requirements, data sources, processing logic, and output destinations.
2
Architecture Design
Design streaming topology, partition strategy, processing pipeline, and exactly-once guarantees.
3
Implementation
Build event producers, streaming processors, consumers, and real-time analytics dashboards.
4
Testing & Validation
Load test with production-like event rates, validate ordering guarantees, and test failure recovery.
5
Production & Monitoring
Deploy with consumer lag monitoring, partition health tracking, and automated scaling policies.
Technology Stack
Streaming
Apache KafkaRedpandaKinesisPulsar
Processing
Apache FlinkSpark StreamingKafka StreamsKSQL
CDC
DebeziumAWS DMSLogical ReplicationMaxwell
Analytics
ClickHouseApache DruidTimescaleDBGrafana
Industries We Serve
FinTechAdTechIoTGamingE-CommerceLogisticsTelecom
Ready to Process Data in Real-Time?
Let's build a streaming architecture that delivers data when it matters most — in real-time.
Frequently Asked Questions
We build real-time data pipelines using Apache Kafka, Apache Flink, Apache Spark Streaming, and AWS Kinesis. Our choice depends on your latency requirements, throughput needs, and existing infrastructure.
MicrocosmWorks offers real-time data processing development at $25-$50/hour. The total project cost depends on data volume, number of sources, processing complexity, and whether you need exactly-once delivery guarantees.
Yes, we architect real-time analytics solutions using streaming engines like Kafka Streams or Flink combined with time-series databases like ClickHouse or TimescaleDB, delivering sub-second query latency on live data.
We implement windowing strategies with configurable watermarks and allowed lateness thresholds, using event-time processing in Flink or Kafka Streams to correctly handle out-of-order events without data loss.
Absolutely. MicrocosmWorks specializes in building lambda and kappa architectures that unify real-time stream processing with existing batch pipelines, ensuring consistent results across both processing modes.